Intelligence
in
your
pocket.
Purely
on-device.
Run quantized GGUF models (from lightweight 135M up to 8B parameters) directly on your smartphone NPU and GPU with native llama.cpp C++ bindings on background isolates. Absolute privacy, streaming tokens, multimodal generation, and zero data leaves your phone.
A New Angle of Mobile Intelligence. Pure Silicon Acceleration.
Interactive Video Walkthrough • 1280x2856 Authentic Android Screen Captures from Thinkpocket AI
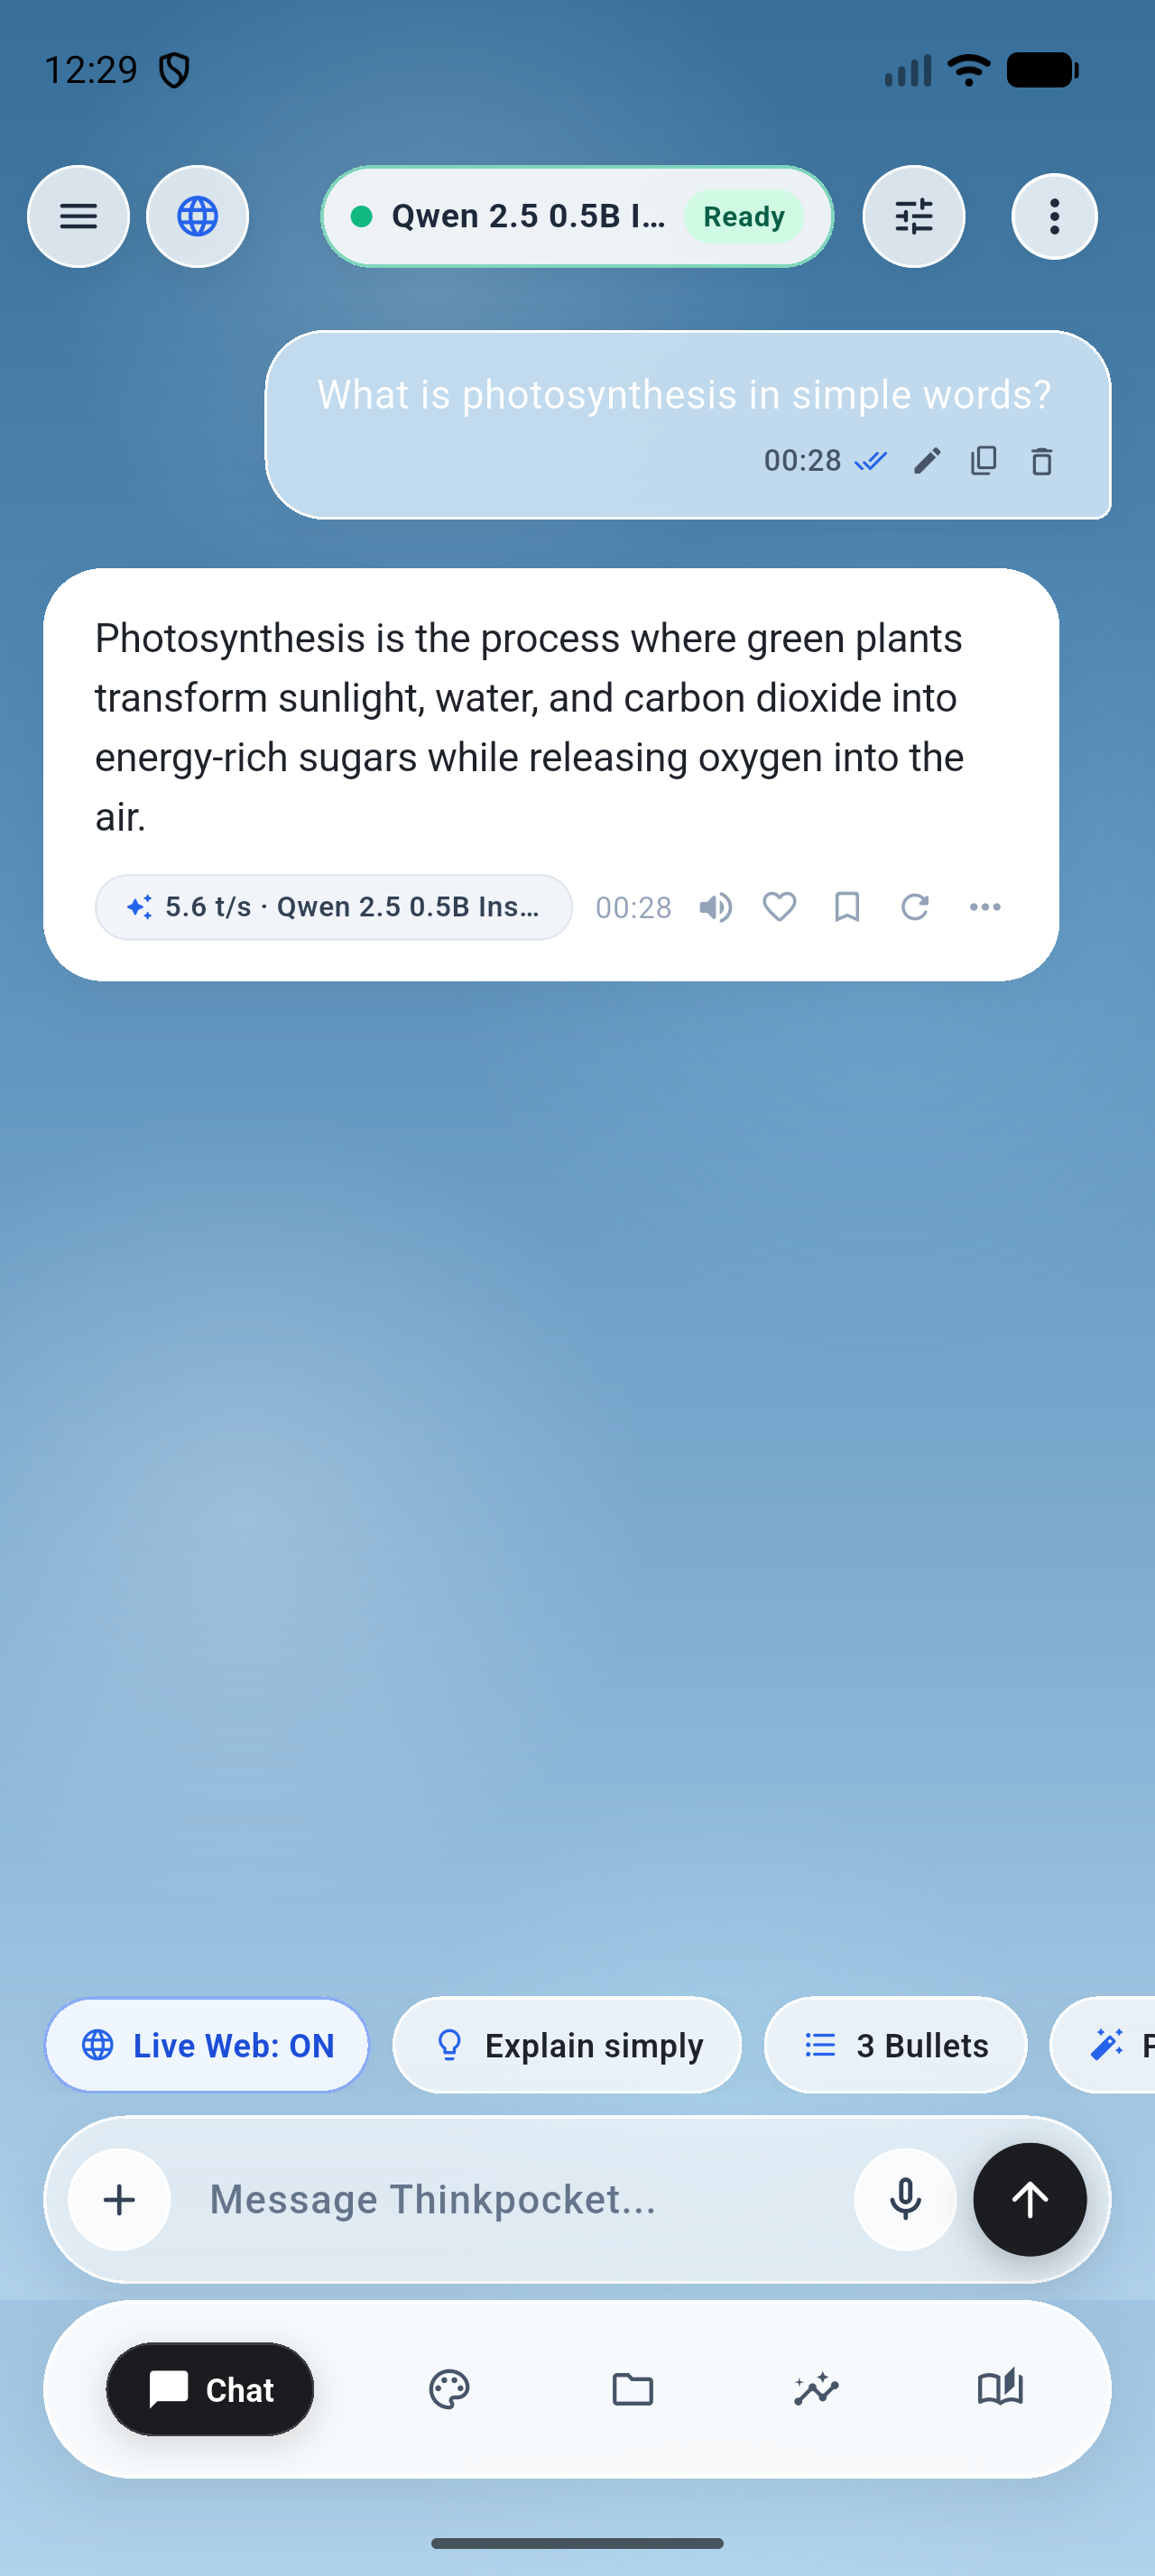
Experience on-device streaming without cloud latency.
See how Thinkpocket AI generates answers token-by-token using native llama.cpp isolates without waiting for a remote cloud server.
Power and absolute air-gapped privacy without compromise.
Every layer of Thinkpocket AI is architected from clean C++ bindings to dedicated Flutter Isolates for buttery-smooth mobile execution.
Dedicated Dart Isolate & JNI Architecture
Heavy LLM inference runs on a background isolate thread wired directly to libllama.so and official fllama JNI bindings. Features asynchronous FIFO memory locking—strict single-model invariant, zero memory leaks, and locked 120Hz Flutter UI.
Zero Telemetry. Zero Cloud.
Turn on Airplane Mode. Pull out your SIM card. Thinkpocket AI continues answering with zero loss of functionality. No analytics SDKs, no external servers, no subscriptions.
Diffusion, Motion & Speech
Generate images with MobileDiffusion Lite, synthesize procedural video loops with AnimateDiff, and transcribe neural speech with Whisper Tiny on-device.
1-Tap GGUF Explorer
Directly explore and download thousands of open models from Hugging Face. Includes background downloading with pause/resume and chunk integrity verification.
Offline Contextual RAG
Store notes, research, and confidential documents in SQLite with Drift. Attach docs directly to your chat context for pinpoint semantic question answering.
Offline Voice Notes & Whisper
Record voice memos with live amplitude waveforms and on-device playback. Transcribe speech into text locally with Whisper Tiny without cloud processing.
Design in motion. Hardware accelerated 120Hz ProMotion animation.
Experience true Jitter-grade animation curves directly in your browser. Choose an on-device UI component and trigger hardware-accelerated spring animations.
"Quantum entanglement allows particles to share states instantaneously across arbitrary physical distances."
Optimized for your hardware.
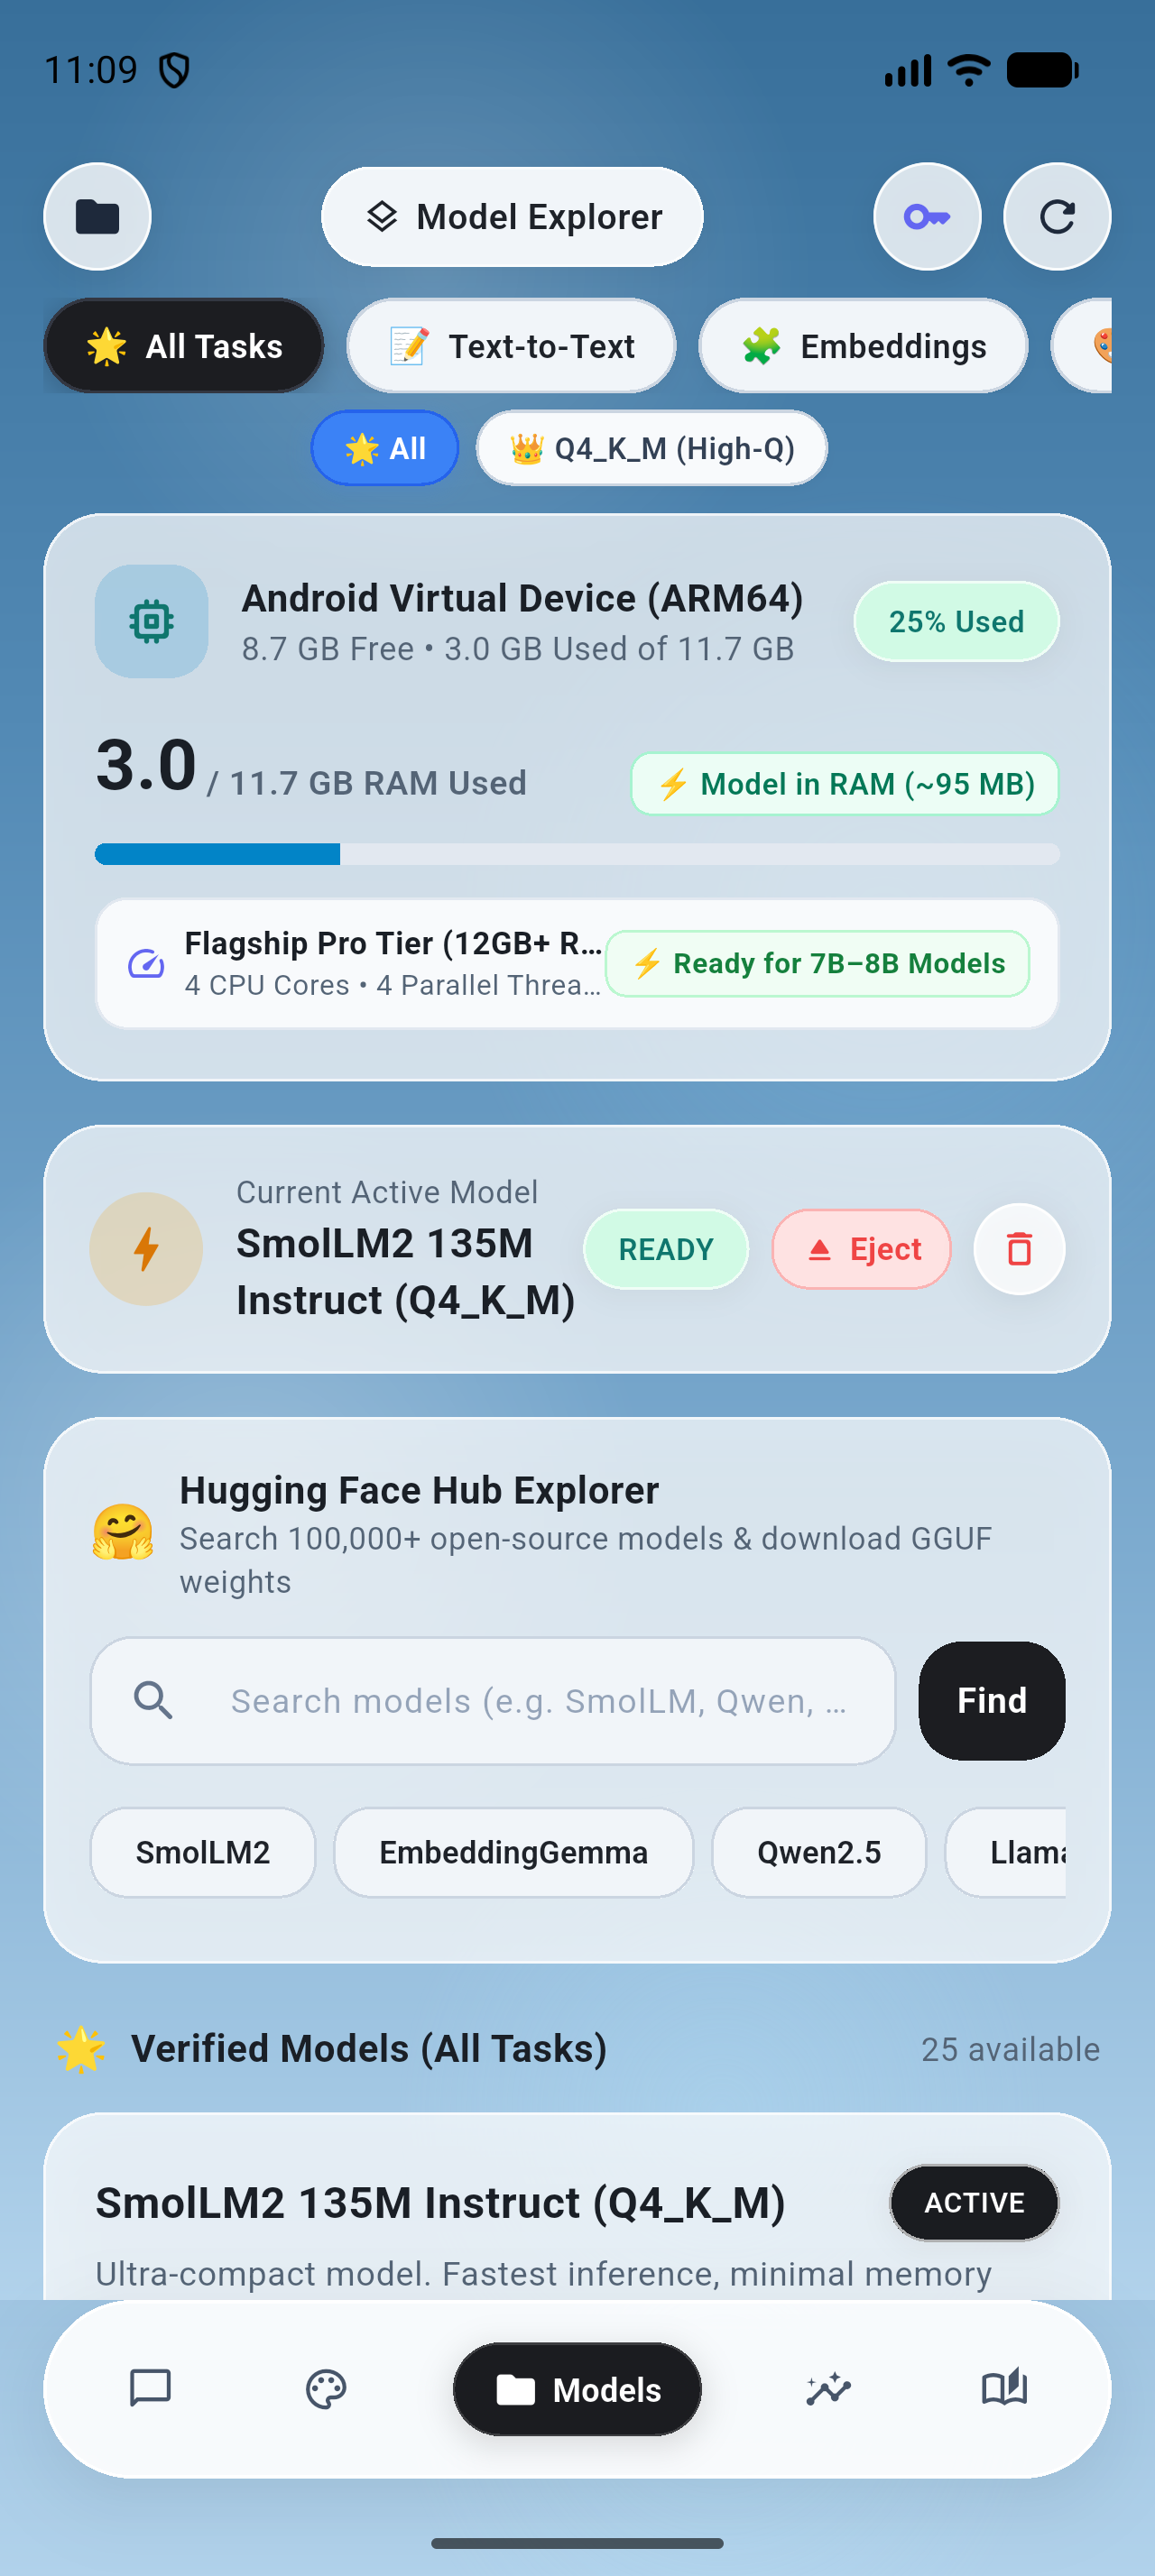
From 95MB up to 8B Parameters.
Thinkpocket AI features pre-configured GGUF models tailored for smartphone RAM capacities, with smart memory safety validation before loading.
SmolLM2 135M Instruct
Ultra-compact language model. Instantaneous inference and negligible memory footprint, ideal for low-spec phones.
SmolLM2 360M Instruct
Balanced small model for reasoning, concise answers, and exceptional battery conservation during extended chat.
Qwen 2.5 0.5B Instruct
High quality multilingual fluency, math reasoning, and coding syntax in a sub-billion parameter package.
Meta Llama 3.2 1B
Meta's specialized mobile model with superior natural dialogue, structured output formatting, and prompt following.
Google Gemma 2 2B
Google DeepMind's flagship conversational model for deep knowledge questions, essay writing, and analytical tasks.
DeepSeek-R1 Distill 1.5B
DeepSeek-R1 distilled reasoning model with Chain-of-Thought (CoT) multi-step thinking. Solves logic, coding puzzles, and math step-by-step.
Qwen 2.5 1.5B Instruct
Alibaba's powerhouse small LLM with exceptional coding syntax, mathematics, and logical multi-turn dialogue on mobile NPUs.
Meta Llama 3.2 3B
Meta's flagship mobile 3B parameter model offering state-of-the-art multilingual conversation, rich summarization, and task orchestration.
Phi-3.5 Mini 3.8B
Microsoft's high-tier reasoning powerhouse with 128k context support, superb mathematical deduction, and deep logic synthesis.
01-AI Yi 6B Chat
Desktop-grade 6B parameter bilingual model delivering deep scientific reasoning, encyclopedic domain knowledge, and comprehensive coding on flagship mobile hardware.
Meta Llama 3.1 8B Instruct
Meta's industry-standard 8B foundation model executing natively in smartphone silicon. Features massive 128k context support, state-of-the-art multilingual knowledge, and desktop-grade reasoning with zero cloud traffic.
Qwen 2.5 7B Instruct
State-of-the-art 7.6B parameter foundation model running directly in smartphone silicon. Superlative code generation, deep multi-step reasoning, and complex math with zero cloud roundtrips.
DeepSeek-R1 Distill 7B
Full-precision 7B reasoning foundation model with exhaustive Chain-of-Thought thinking. Unlocks graduate-level STEM deduction directly on high-RAM mobile silicon.
Qwen-Image 2.1 Turbo
Alibaba's state-of-the-art 7B Image Diffusion Transformer quantized by Unsloth. Delivers breathtaking on-device text-to-image generation, typography, and anime art with zero cloud latency.
MobileDiffusion Lite
Sub-second mobile on-device latent diffusion UNet for instant artistic illustration and photo synthesis.
MobileDiffusion Tiny
Ultra-lightweight on-device diffusion UNet for instant thumbnail synthesis and ultra-low battery consumption.
AnimateDiff Motion LoRA
Procedural open video motion module for rendering cinematic camera zooms and animated looping sequences.
AnimateDiff Motion Lite
Smooth multi-frame motion module for rendering continuous looping video sequences directly on mobile GPUs.
Whisper Tiny Speech
Ultra-fast on-device neural voice transcription and speech comprehension without sending audio to remote APIs.
EmbeddingGemma 2
State-of-the-art vector embedding model for high-accuracy semantic search, private document chunking, and local RAG.
Crafted with serene aesthetics and tactile glassmorphic refinement.
Experience our pastel glassmorphic design system with haptic feedback, real-time speed badges, and intuitive model switching.
Serene Chat & X Design Language
Daylight sky glassmorphism with X-style post actions (Like, Bookmark, TTS voice readout, Regenerate, Delete), double checkmarks (✓✓), prompt spark chips (Live Web: OFF, Explain simply, 3 Bullets), and live word/token estimation in local SQLite.
Hugging Face GGUF Search
Direct in-app Hugging Face Search & explorer for Qwen, SmolLM, Llama, DeepSeek, and Whisper. Download GGUF models in the background with automatic RAM safety verification.
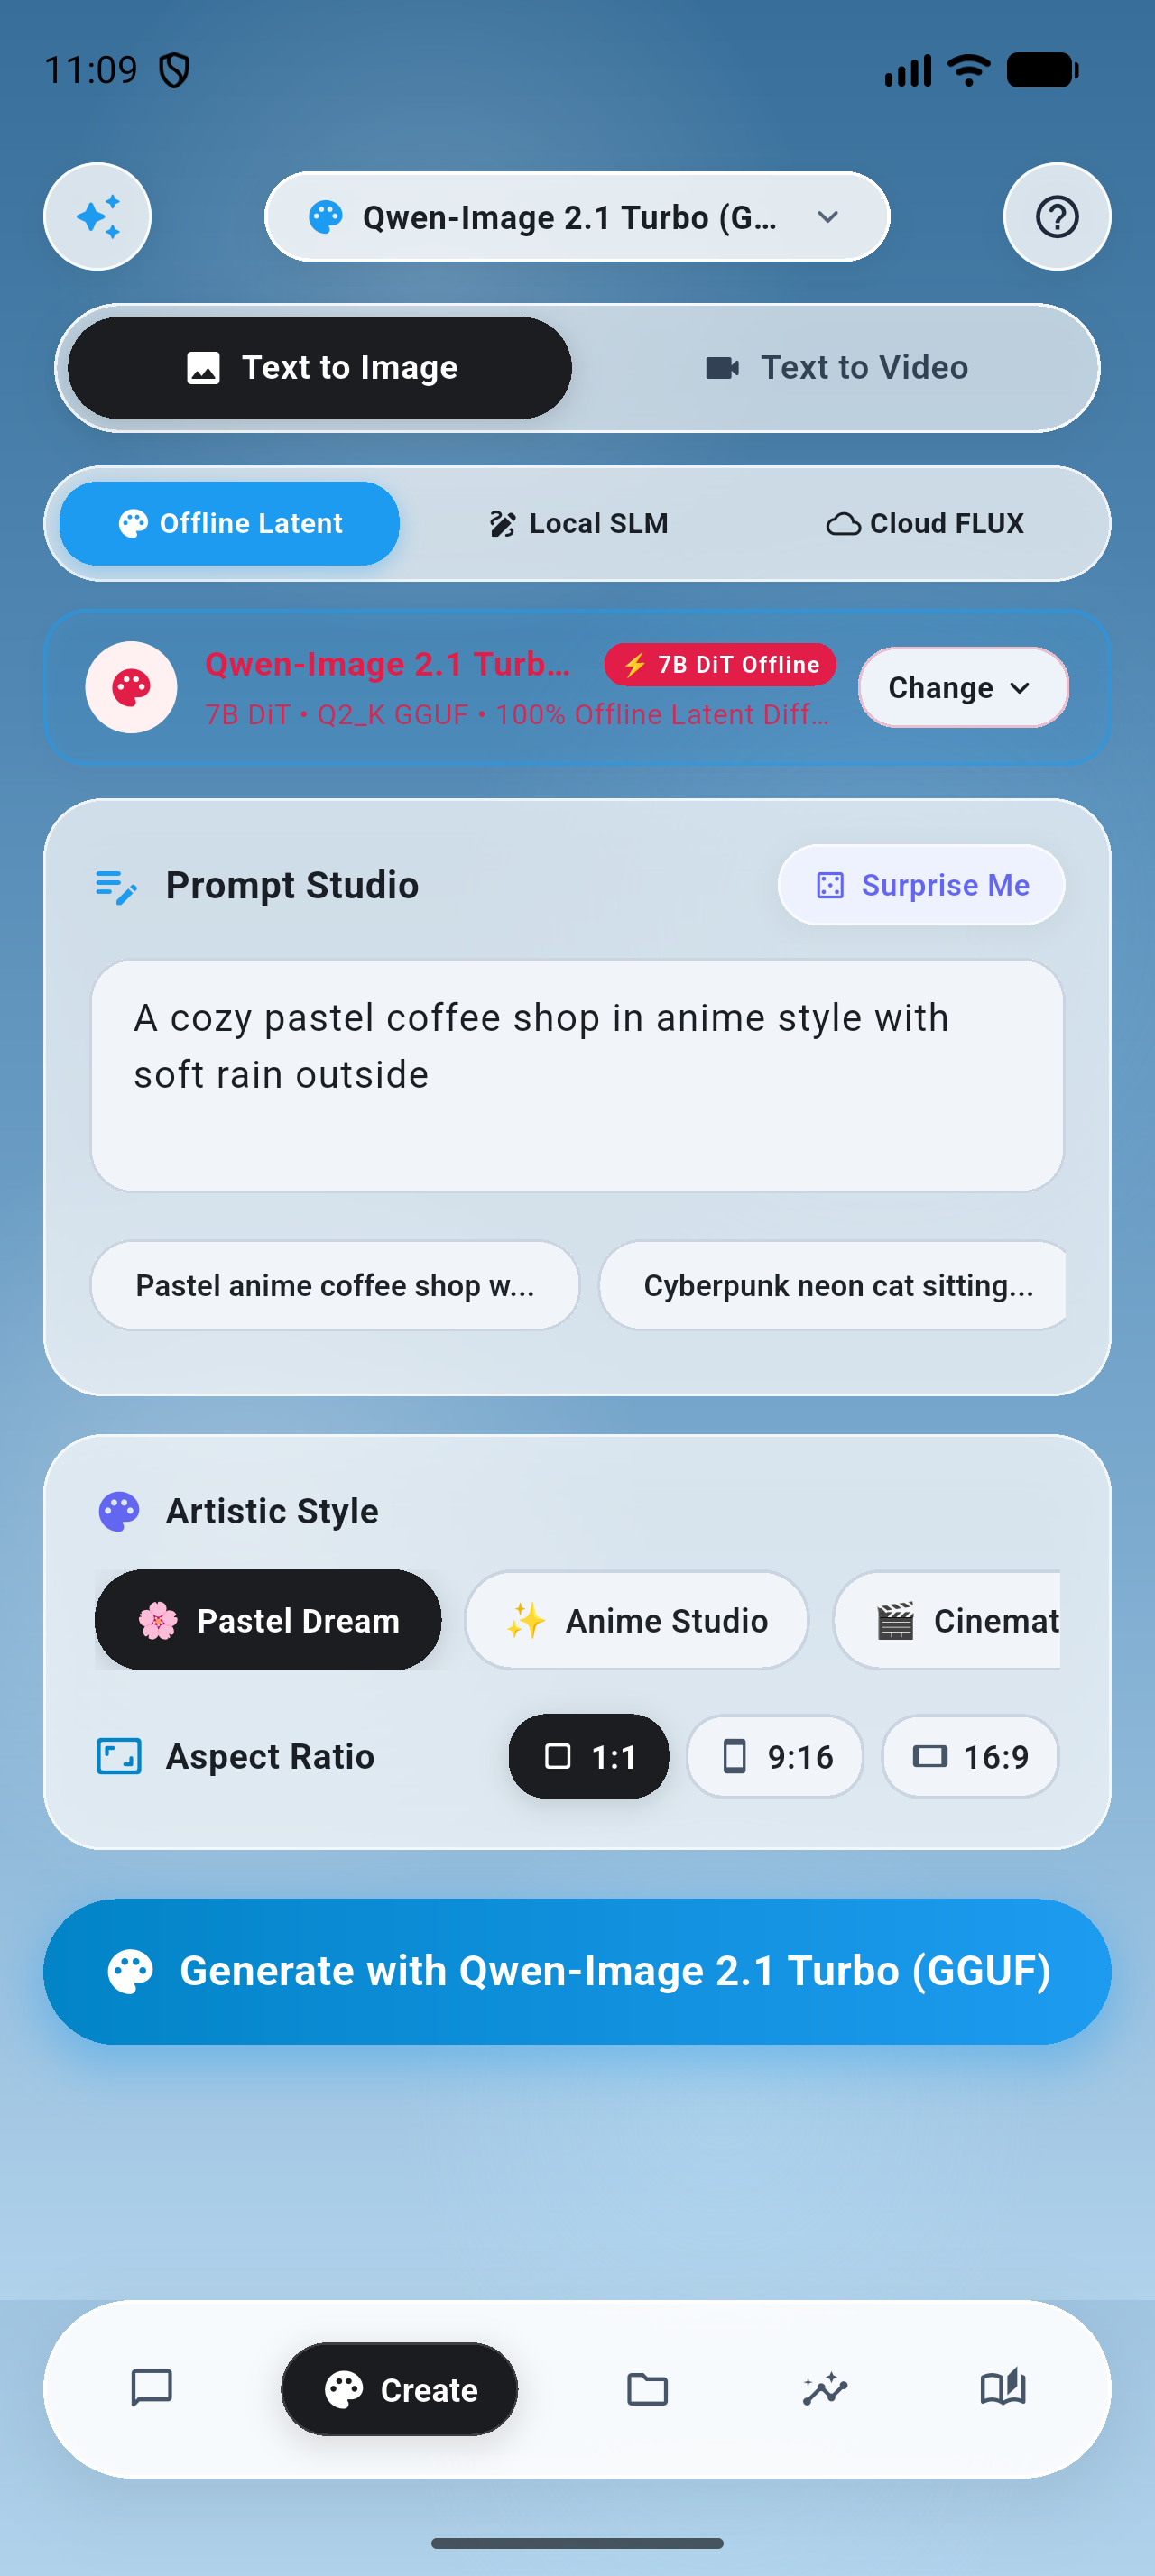
3-Engine Multimodal Studio
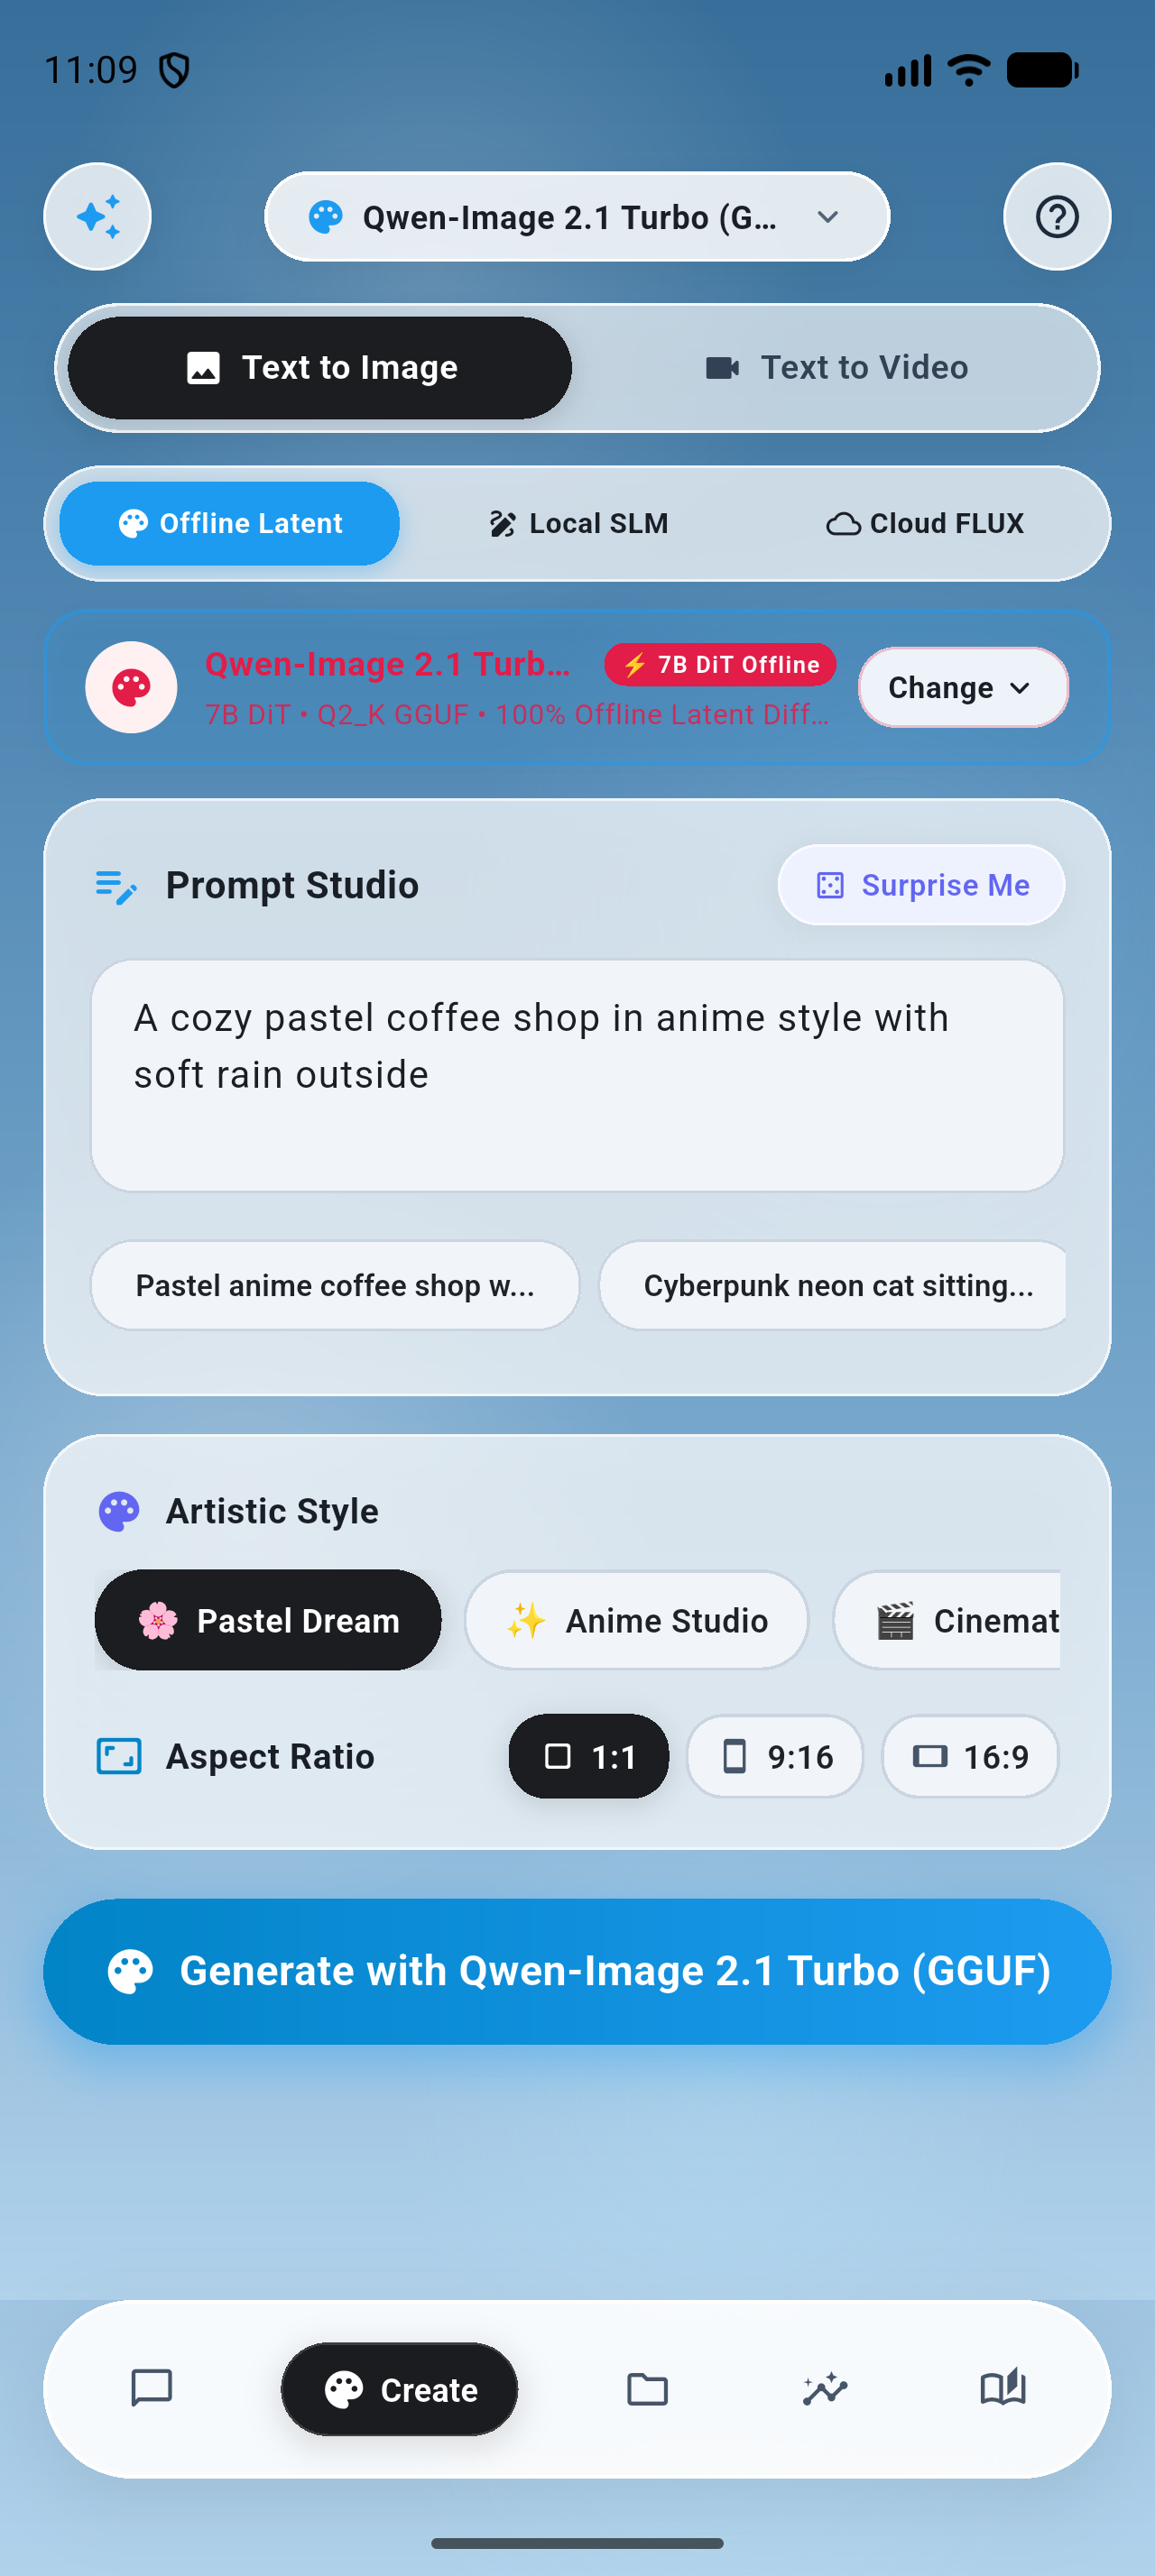
Choose between 100% Offline Latent Diffusion (Qwen-Image 2.1 Turbo 7B DiT, MobileDiffusion Lite), Local SLM Vector SVG Synthesis with live code view, and Cloud FLUX. Includes Text-to-Video with AnimateDiff Motion LoRA and 1:1, 9:16, 16:9 aspect ratios.
Creation Bottom Sheet
Tactile bottom-sheet studio interface with modality toggles, negative prompts, resolution aspect ratios, and seed generation.
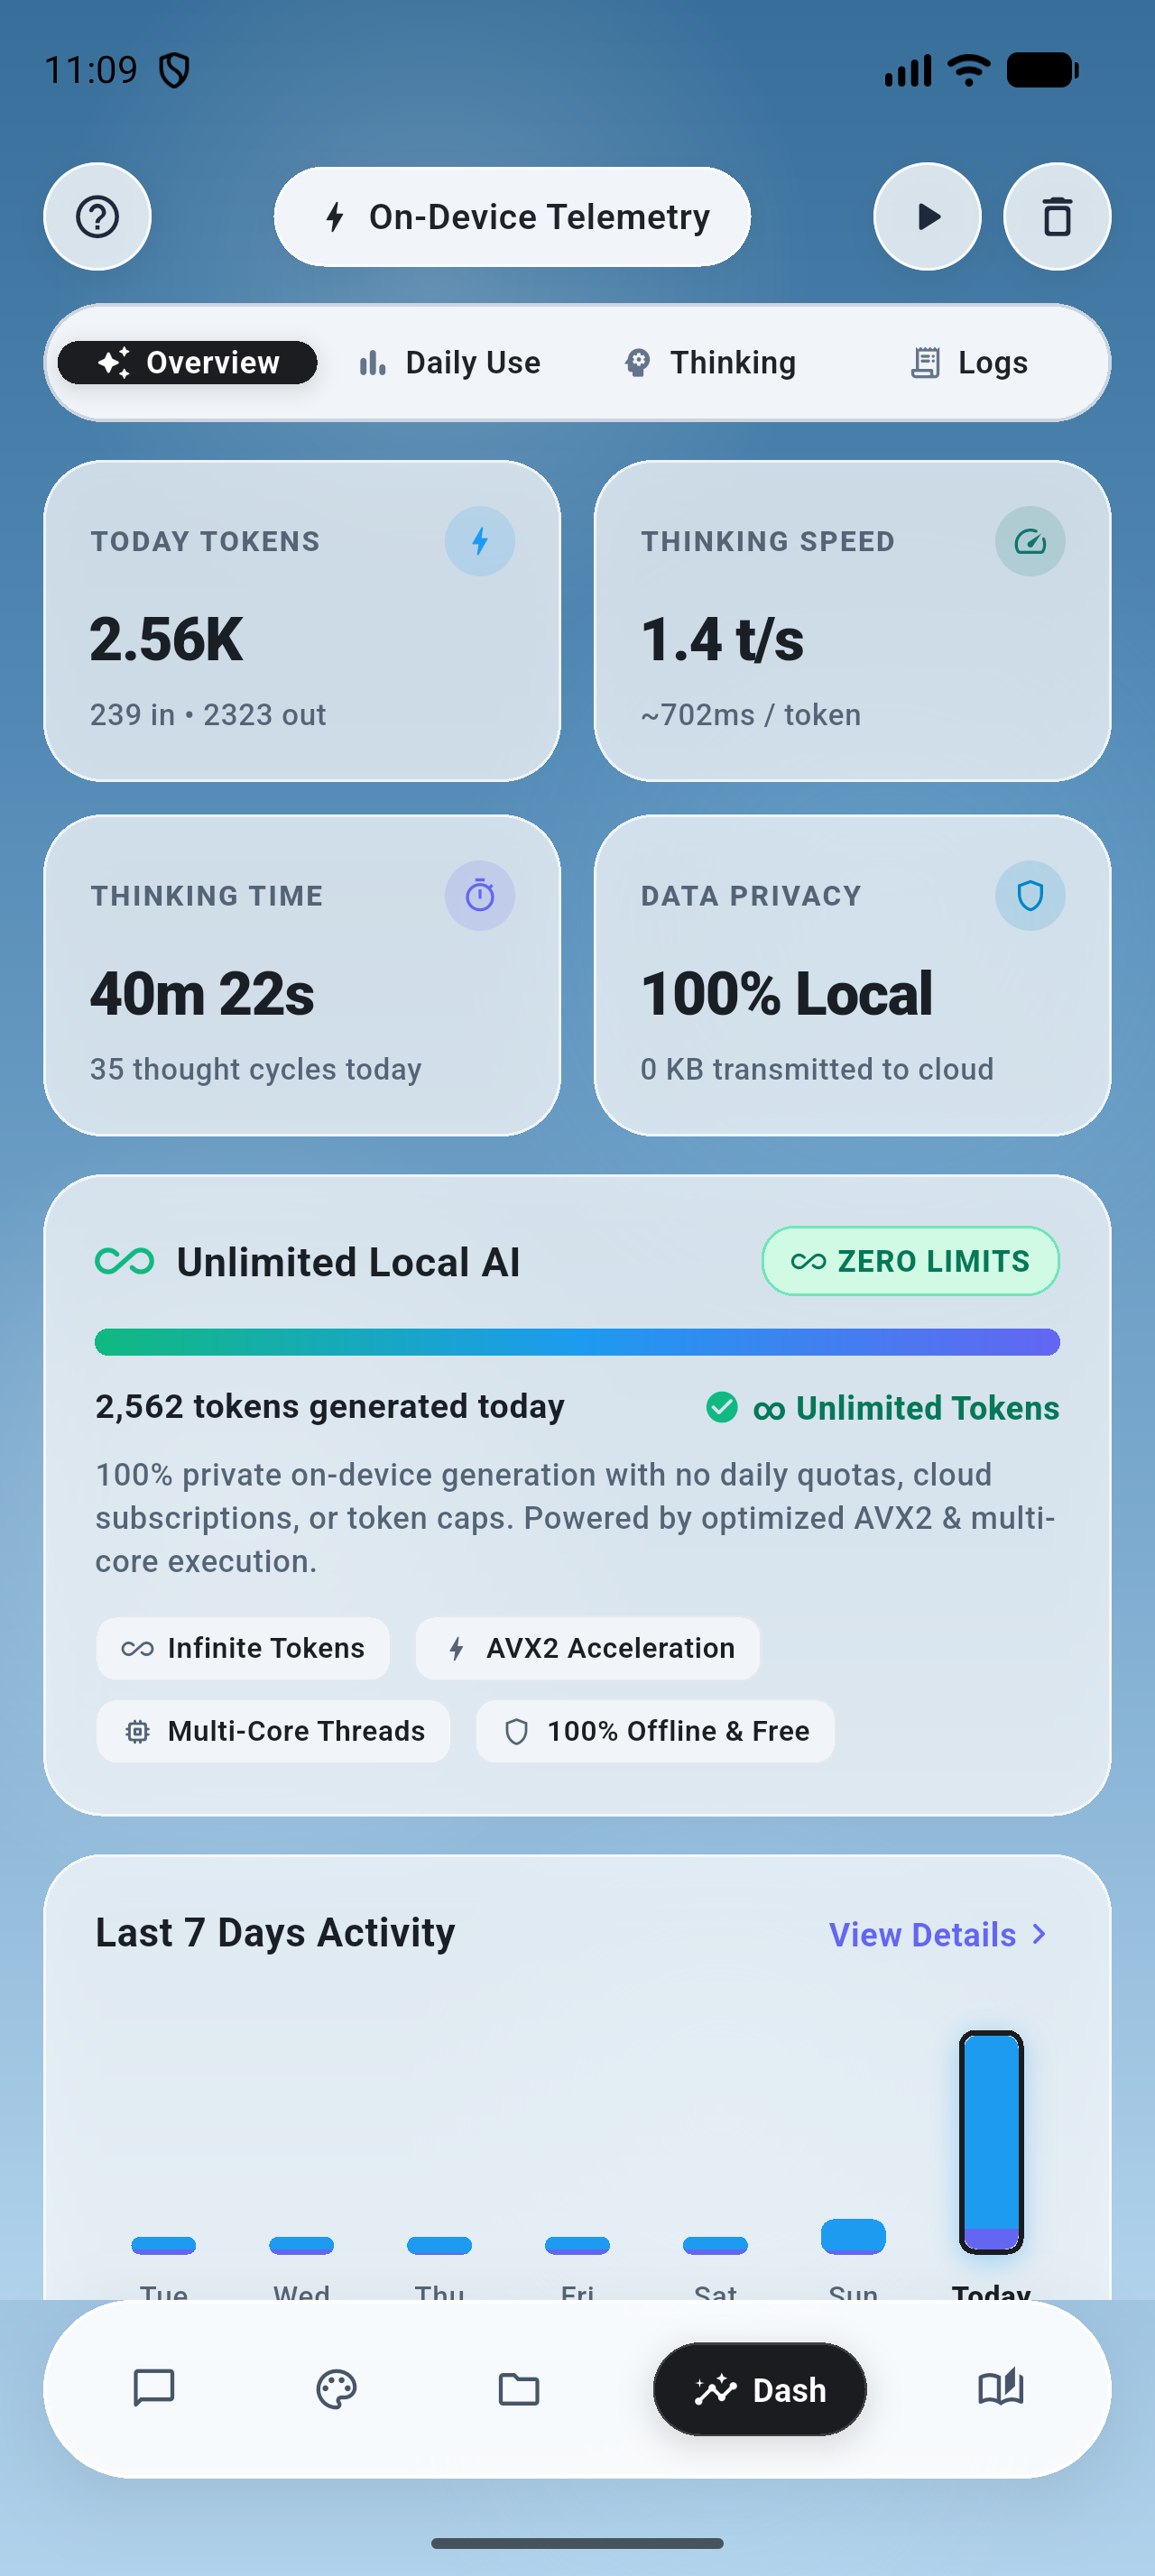
Unlimited Local AI & Telemetry
Real-time on-device telemetry verifying 100% local execution (0 KB transmitted). Features Unlimited Local AI with ZERO LIMITS, no token caps, AVX2 acceleration, multi-core CPU tuning, and 0 MB RAM startup memory guarantee.
Pocket Vault & 384-D Vector RAG
Store encrypted notes, code snippets, and chat summaries with automatic categorization. Built-in Private Vector DB with 384-Dimensional Cosine Index for 100% offline semantic retrieval and 1-tap "Chat with Doc".
Thinkpocket AI versus legacy cloud AI. Sovereign intelligence.
Compare why true on-device processing represents the future of personal privacy and computational autonomy.
| Feature |
 Thinkpocket AI |
Cloud AI Apps (ChatGPT / Claude) |
|---|---|---|
| Data Privacy | 100% On-Device (0 KB sent) | Sent to third-party data centers |
| Subscription Cost | $0 Forever (Free & Open Source) | $20 – $200 / month recurring |
| Internet Connection | Never Required (Air-Gapped) | Fails completely without internet |
| Model Selection | Any GGUF model on Hugging Face | Vendor locked to single model family |
| Data Retention & Training | Never trained on, never logged | Stored on servers for model retraining |
| Censorship & Outages | Zero downtime, zero external filtering | Subject to server downtime and rate limits |
Precision engineering.
From C++ to Dart.
Clean Architecture separation across presentation, domain, and native C++ runtime.
Compiled using Android NDK 28 with CMake. Leverages ARM64-v8a NEON SIMD vector extensions for ultra-fast on-device matrix multiplication.
All token generation occurs on an isolated memory thread. Zero UI blocking or frame dropping on 120Hz displays.
Full local session persistence, token analytics, audit logs, and document chunk storage completely offline in encrypted SQLite.
Targeted to API 36 with 64-bit ABI support. Dynamically checks available RAM to prevent Out-Of-Memory (OOM) crashes.
Frequently Asked Questions
Everything you need to know about running Thinkpocket AI on your phone.
The next era of mobile AI
is almost here.
Thinkpocket AI is currently preparing for official release on the Google Play Store. 100% on-device neural inference, zero subscription fees, and complete air-gapped privacy.